← All workPrivate AI app · runs on my PC
Local AI
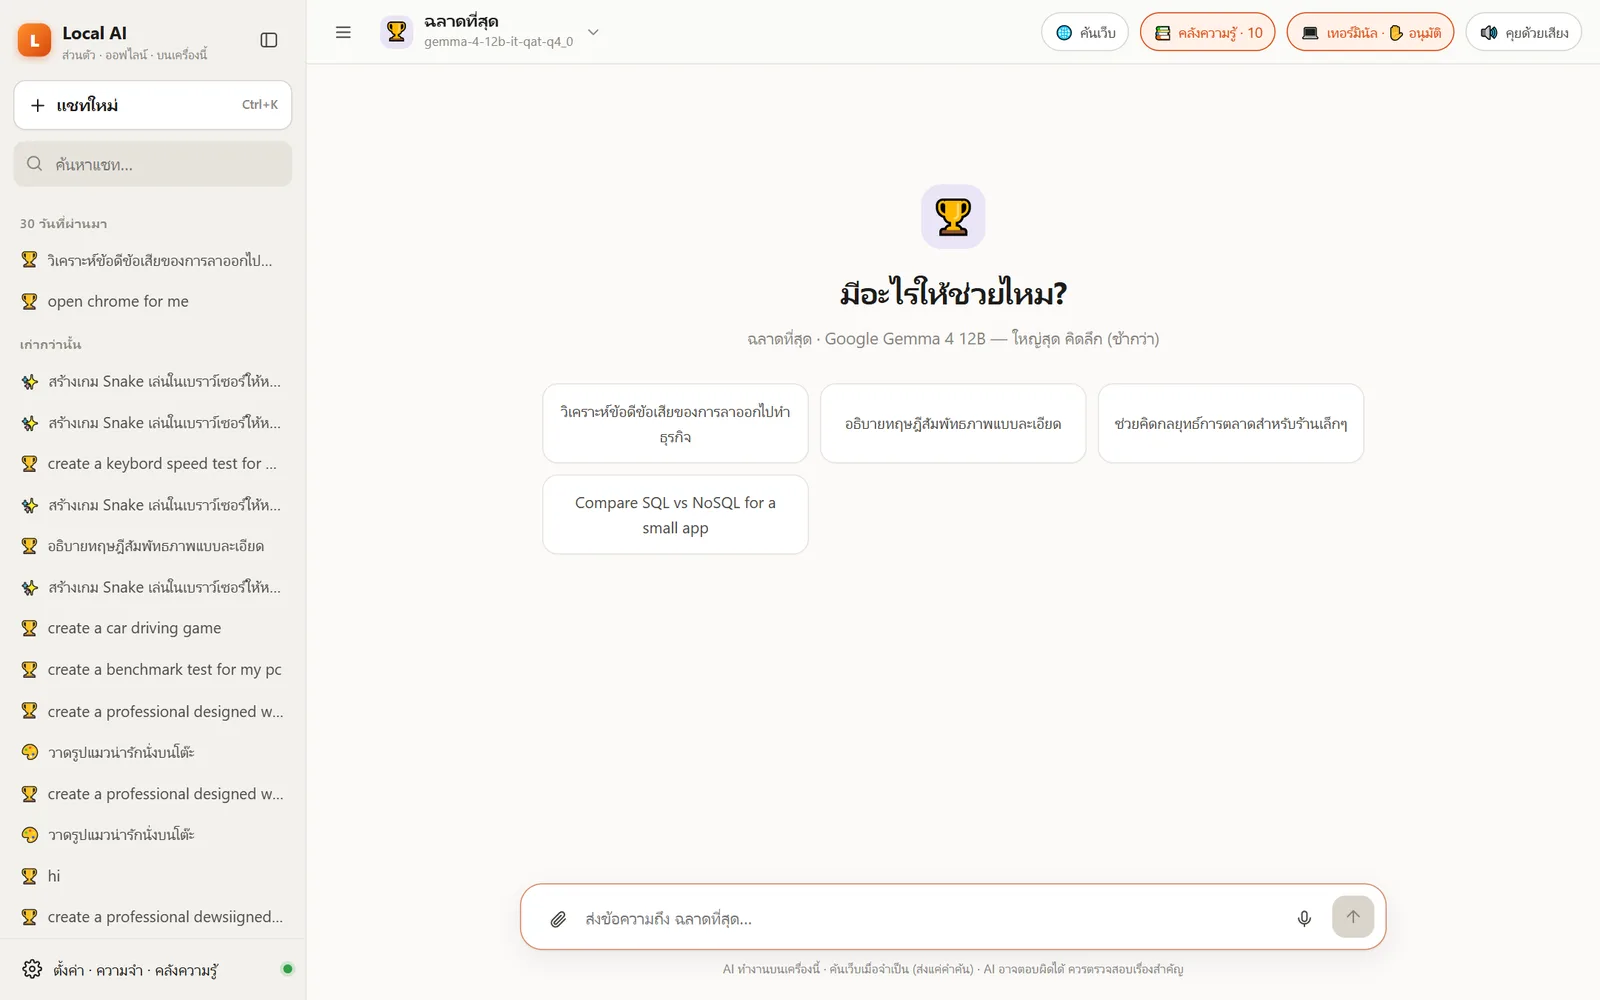
My own ChatGPT-style app that runs fully on a home PC: chat with several open models, photos, voice, image generation, web search, a knowledge folder and a terminal it can use with my approval.
6local models to switch between
0data leaves the PC
~0.5 svoice to text on GPU
8 GBgraphics card it fits in
I wanted an AI that is private and free to run, on my own graphics card — and not just a wrapper around Ollama. I built the engine on llama.cpp and diffusers, and a web app around it that opens like a desktop app.
It also powers other work: the clinic dashboard sends AI requests to it first through a secure bridge.
Inside Local AI
Chat with the right model
- Models: Qwen3-8B (general / coding), Qwen3.5-4B (fast), Gemma 4 (vision), Gemma 4 12B (smart) — switch mid-chat.
- "Auto" picks for you; picture requests are handed to the image model automatically.
- Web search (DuckDuckGo + article extraction) when the question needs fresh facts, with sources shown as cards.
- Thai-first: fixes for models that drift into other languages.
Photos, voice and images
- Send a photo and Gemma 4 vision describes or reads it.
- Push-to-talk voice: Whisper large-v3-turbo on the GPU turns speech into text in about half a second; answers can be read aloud.
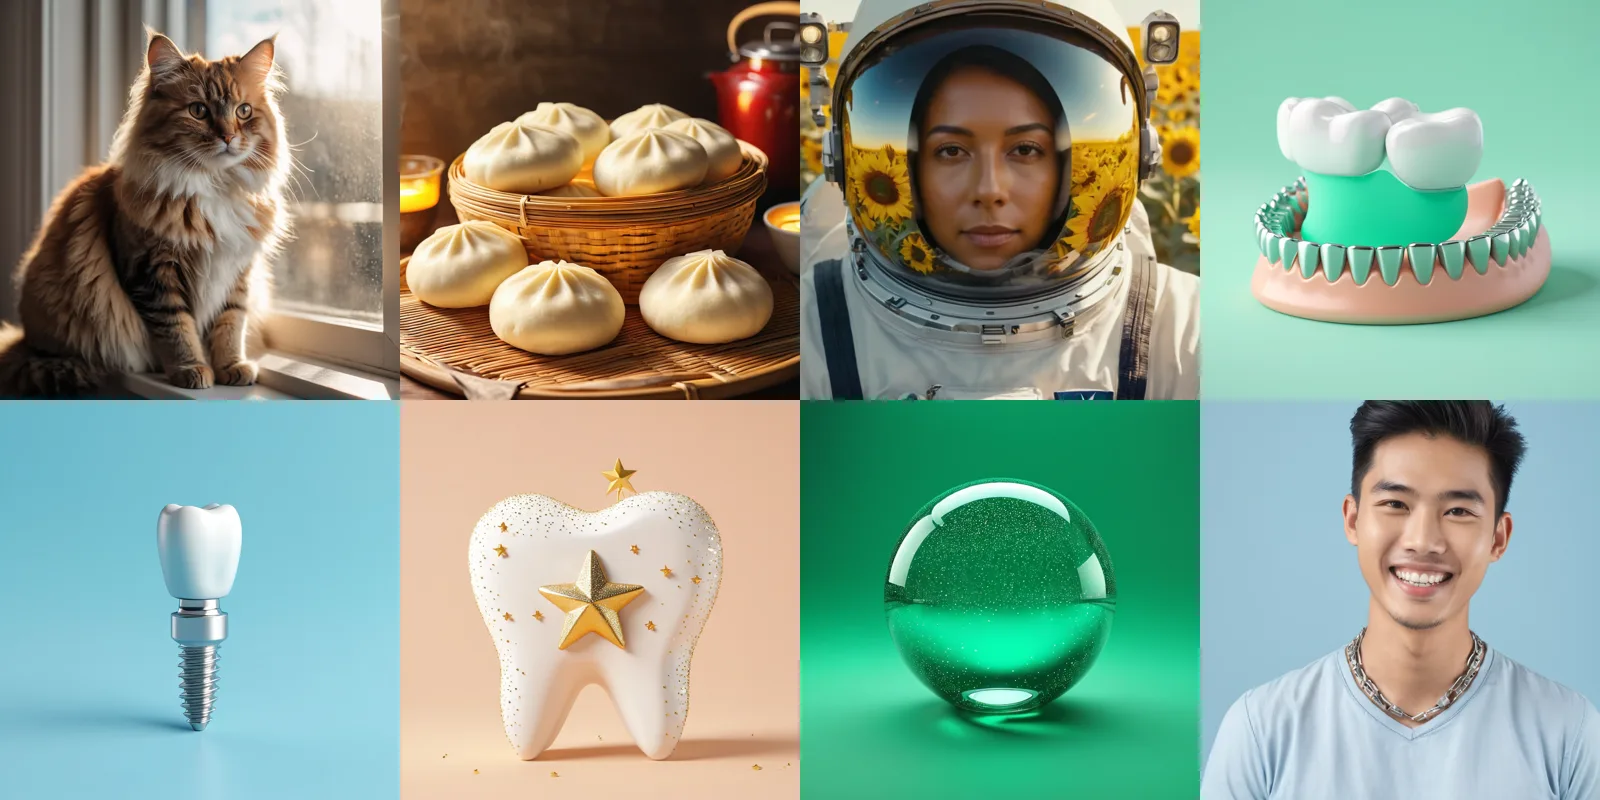
- Image generation with SDXL in a separate worker process, so memory is fully freed after each picture (pictures above were made on the PC).
It remembers and learns
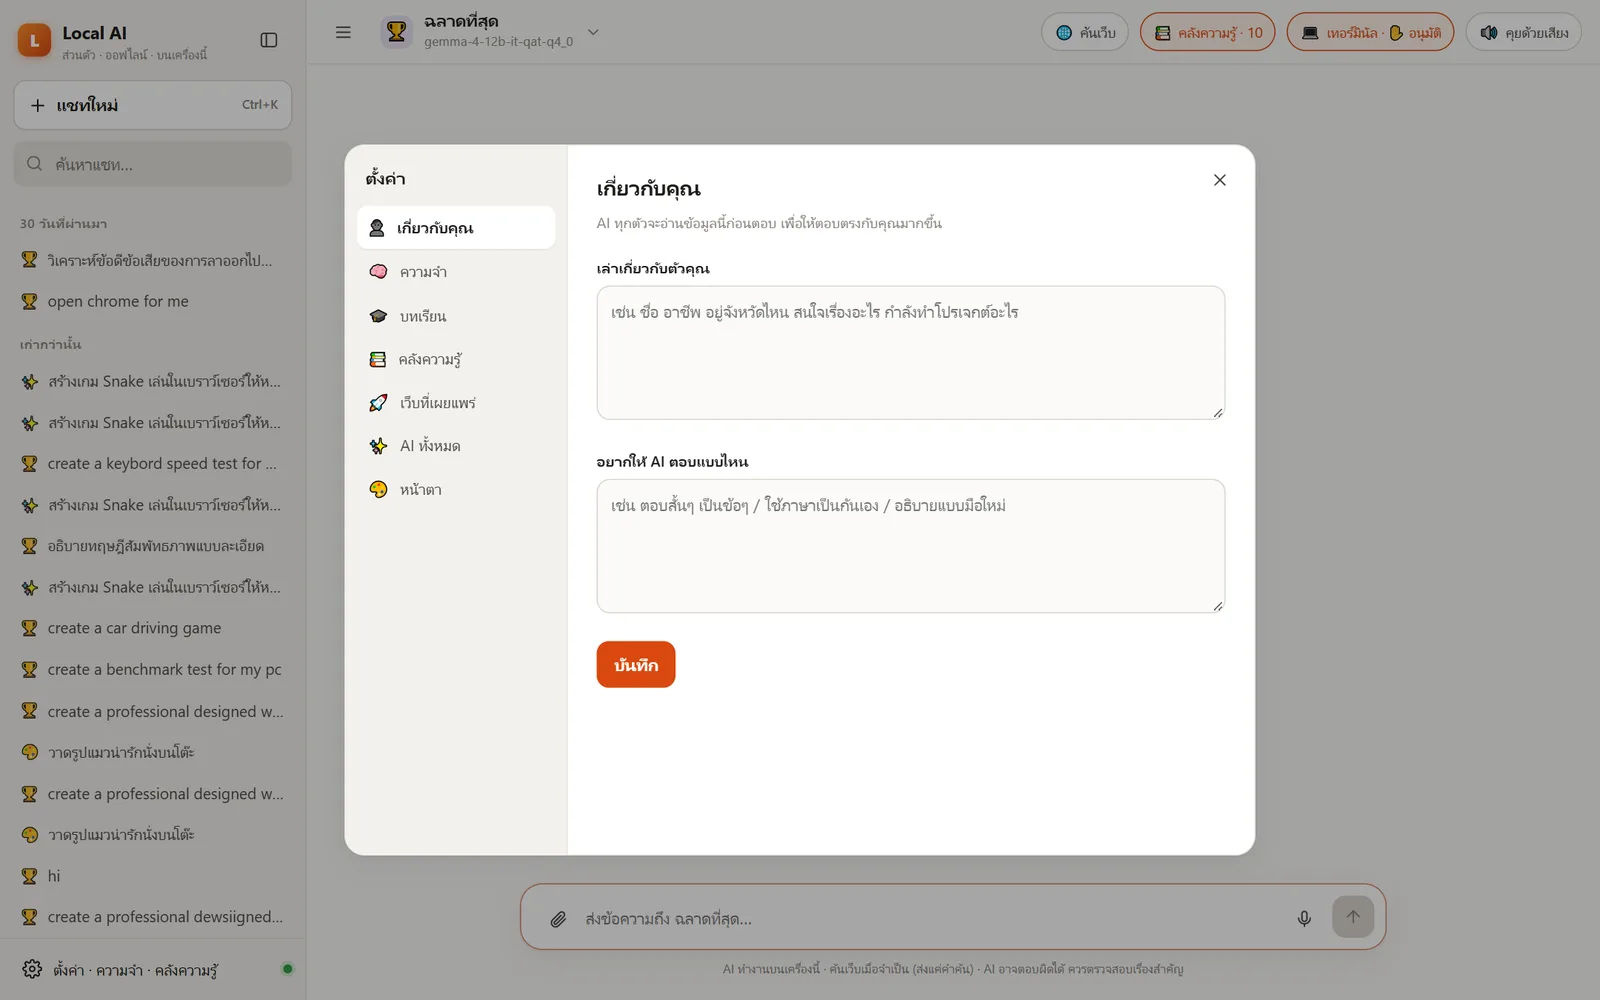
- Memory: facts about me are pulled from my messages and de-duplicated with embeddings.
- Knowledge folder: drop PDFs / Word files in and it answers from them (retrieval with bge-m3).
- 👍 / 👎 / ✏️ feedback becomes lessons that change how similar questions are answered later.
A terminal it can use — with my approval
- It can run PowerShell commands, but every command is shown first; risky ones (delete, registry, shutdown) need typing a confirm word.
- When asked to build a web page or game, it writes it, tests it in a headless browser, and can publish it on the home network.
- Game mode: when a full-screen game is running, it unloads models and steps aside so the PC doesn't lag.
Stack
Pythonllama.cpp (CUDA)Qwen3 / Gemma 4Stable Diffusion XLfaster-whisperbge-m3 embeddingsFlaskVanilla JS UI
Runs locally, so there is no public link — happy to demo it live.